← all events / hacktober-hackshare x · linkedin ·
● registrations openhackathonin-person

hacktober hack

a hackathon on building quality agents. every team starts from the same flaky agent, and a hidden eval suite decides whose holds up.

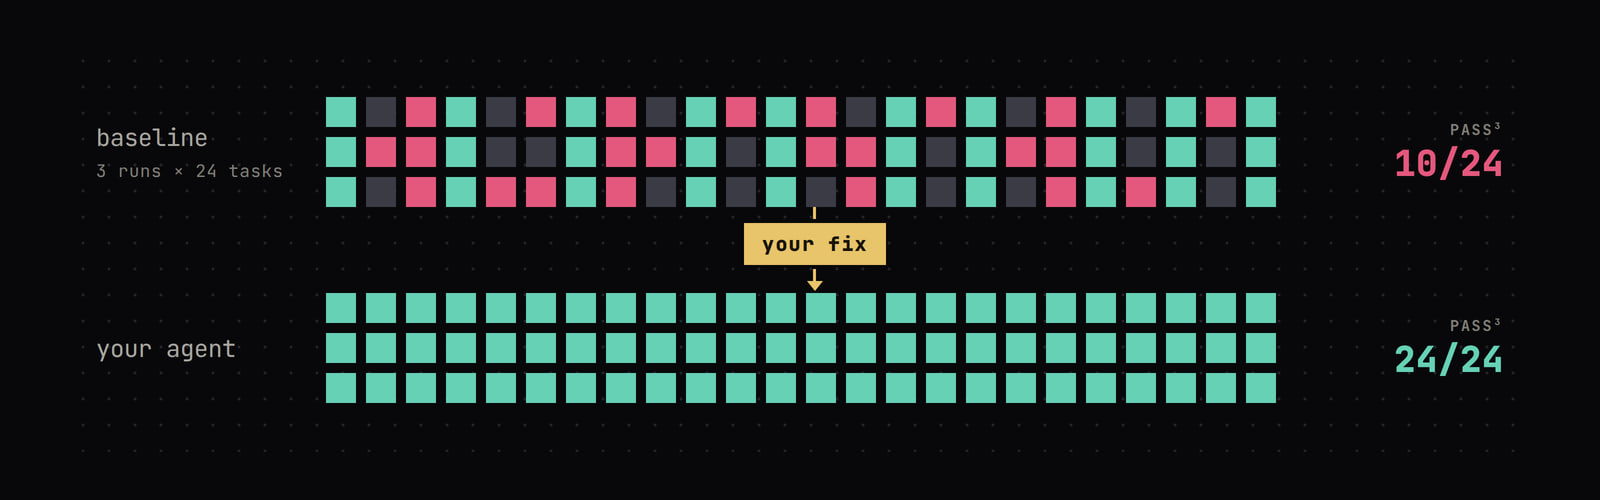
same agent, same model, 1 h 50 min. change anything around the model: prompts, tools, validation, retries, policies. then every hidden task runs three times, and it only counts if it passes all three. solo or in a team of up to three, judged on the numbers.

co-hosted byfailproof aiquad ai

what it's about

a quality agent does the job right every time, not once in a demo. when agents fall short, the model can usually do the work: a tool returned something odd, a check got skipped, or one lucky run hid two bad ones.

hacktober hack gives every team the same open-source agent, the same model and a public eval suite, then 1 h 50 min to build quality into it. at code freeze we run a hidden eval suite against every submission, three times per task.

  1. 01get the agent

    one open-source agent and model for every team, revealed at kickoff, with a public eval suite and a baseline score to beat.

  2. 02build in quality

    prompts, tools, validation, retries, policies: change anything around the model. not the model, not the evals.

  3. 03prove it

    add the eval cases that catch what you fixed. the hidden suite scores your agent; your cases score your evals.

good forengineers building agentssolo or teams of up to three

co-hosted with quad ai

quad ai · school of technology · bengaluru

graduate unignorable.

quad ai school of technology runs industry-built programmes: a b.tech in computer science engineering with ai & ml, and an ai-integrated management programme, with live projects, internships, hackathons and masterclasses alongside. it has campuses in bengaluru, mangaluru and patna.

based in
bengaluru
programs
b.tech cs (ai & ml) · ai-integrated management
www.quadcse.com ↗

how the winner is picked

to winthe agent that holds up best on the hidden eval suite: the share of tasks it passes on all three runs.

  • reliability · 80 pts

    every hidden task runs three times and counts only if all three pass. a lucky run is not a fix.

  • overall performance

    a run over the call, time or token limit is a failed run, so a fix that triples the cost does not score.

  • your eval suite · 20 pts

    up to ten cases of your own. each counts when the baseline fails it and your agent passes it every time.

ties go to the lower cost per task. hardcoding the public tasks scores zero on the hidden ones.

how the day runs

all times ist · subject to change
  1. 15 min
    doors open

    grab a seat, find a team, and get your laptop and github ready.

    arrive
  2. 15 min
    kickoff

    meet the agent, its public eval suite and the baseline score, then the rules and how scoring works.

    talk
  3. 1 h 50 min
    build

    build quality into the agent. run the public suite as often as you like; the hosts float the room.

    build
  4. 40 min
    code freeze + demos

    submit your commit. the hidden suite runs while each team shows the failure it fixed and the eval that proves it.

    talk
  5. 30 min
    results + wrap

    hidden-suite scores on screen, the winner called, and the best fixes headed upstream as pull requests.

    social

who's on

  • HOSTNikita Agarwalceo & co-founder @ failproof aixlinkedin
  • HOSTMayank Bansalfailproof ailinkedin
  • HOSTNivedit Jaincto & co-founder @ failproof aixlinkedin

getting there

quad ai hsr campus
27th main rd, beside rbih, 1st sector, hsr layout, bengaluru, karnataka 560102
open in maps ↗

questions

something else? ask on discord →
what is the agent?

it is revealed at kickoff (4:45 pm), so everyone starts from the same place.

it is small, open source and does real work with tools, and it fails the way production agents do: skipped checks, bad tool calls, runs that pass once and fail twice.

what can i change?

anything around the model: the system prompt, tool descriptions, validation, retries, policies and guardrails, planning and memory.

not the model, its settings or the evals. the harness pins the model, and the hidden suite uses new tasks, so tuning to the public ones does not pay.

how is it scored?

80 points for reliability: the share of 40 hidden tasks your agent passes on all three runs, inside the call, time and token limits.

20 points for your evals: up to ten cases you add, each counted when the baseline fails it and your agent passes it every time. ties go to the lower cost per task.

what should i bring?

your laptop, your charger and a github account. come solo or as a team of up to three; you can form one at the door.

we hand out the agent, a model key for your team and the public eval suite at kickoff.

how do i submit?

at code freeze (6:50 pm), send your fork url and one commit sha through the form. that commit is what we score.

after results, open your fix upstream as a pull request: the best fixes and eval cases get merged.

how does registration work?

register on luma. every registration is subject to host approval, so apply early.

it runs at quad ai hsr campus: 27th main rd, beside rbih, 1st sector, hsr layout. the event is also listed on mlh.

what is failproof ai?

failproof is your agent's oversight layer, steering it towards success. it traces your agents, finds failure patterns over time and sets up rules to prevent them from happening again.

the open-source cli is free: npm i -g failproofai.

MORE EVENTS

all events →

your room.
our agents. one night.

contact us